203 results
OCT. 21, 2026 / AI
The Agents CLI Extension System enables developers to use frameworks like LangChain, LangGraph, or custom enterprise stacks while retaining a unified deployment and evaluation workflow. It details a first-party LangChain template that scaffolds, runs, and deploys agents without requiring the Agent Development Kit (ADK). Additionally, it demonstrates how platform teams can author custom extensions to enforce policies such as automated software bill of materials (SBOM) scans during deployment.
OCT. 20, 2026 / AI
TorchTPU integrates a native torch.device("tpu") backend directly into PyTorch, allowing developers to train large-scale models on Google Cloud TPUs without rewriting code in JAX. The TorchTitan TPU fork enhances this with production-grade scaling primitives like SimpleFSDP, Graph Trainer, and custom Pallas kernels that achieve high Model Flops Utilization (MFU) across dense and MoE architectures. Developers can leverage these battle-tested optimization playbooks, recipes, and the Hugging Face modeling backend to efficiently scale their own workloads on TPU infrastructure.
OCT. 20, 2026 / AI
This post announces native PyTorch backends for vLLM and SGLang powered by TorchTPU, enabling developers to run and optimize serving workloads using familiar PyTorch tools. Built in collaboration with open-source project maintainers, these engines include optimized TPU kernel implementations, production-ready features like KV cache management with TPU Sync, and disaggregated serving. Public benchmarks demonstrate state-of-the-art performance and industry-leading cost efficiency on Ironwood TPU across long-context and agentic workloads.

OCT. 15, 2026 / AI
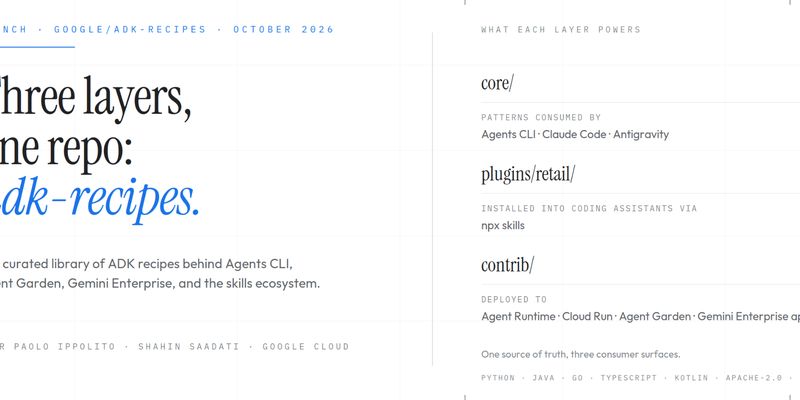
The google/adk-recipes repository unifies Agent Development Kit (ADK) resources into three structured layers—core/, plugins/, and contrib/—serving as a single source of truth for building AI agents. Developers can leverage reference patterns, install modular vertical skills (such as retail product search and virtual try-on) directly into their coding assistants, and deploy production-ready services across multiple languages. This cohesive structure streamlines the entire workflow from initial scaffolding to full deployment on Google Cloud infrastructure.
OCT. 15, 2026 / AI
A practical engineering guide and reference architecture for establishing continuous evaluation pipelines for multi-turn AI agents using Gemini Enterprise Agent Platform, Google ADK, and OpenInference standards.

OCT. 14, 2026 / AI
Apigee hybrid 1.17.0 introduces native Model Context Protocol (MCP) support, enabling the MCP data plane to run directly within your own Kubernetes cluster. This architecture ensures that AI agent request traffic and tool execution remain entirely inside your infrastructure while pulling configuration updates from the control plane. Developers can expose OpenAPI 3.0.x specifications as discoverable MCP tools, leverage existing security policies and API products, and trace end-to-end requests using W3C trace context headers.

OCT. 13, 2026 / Gemini
How our engineering team ran Gemini 4 Argon unattended overnight with .agents/skills and /goal mode to cut in-memory session prep overhead by 40% in long sessions and speed up cold imports by 21% in Google's open-source Python Agent Development Kit (ADK).

OCT. 8, 2026 / AI
How do you keep improving an AI agent after the first 80%, once it serves real production traffic and silent quality regressions return HTTP 200 OK? We are open-sourcing AQuA (Ambient Quality Agent), a reference implementation that runs beside your production agent in Google Cloud, sweeps and verifies failure clusters against conversation transcripts, and diagnoses root causes anchored to the exact deployed source snapshot.

SEPT. 30, 2026 / AI
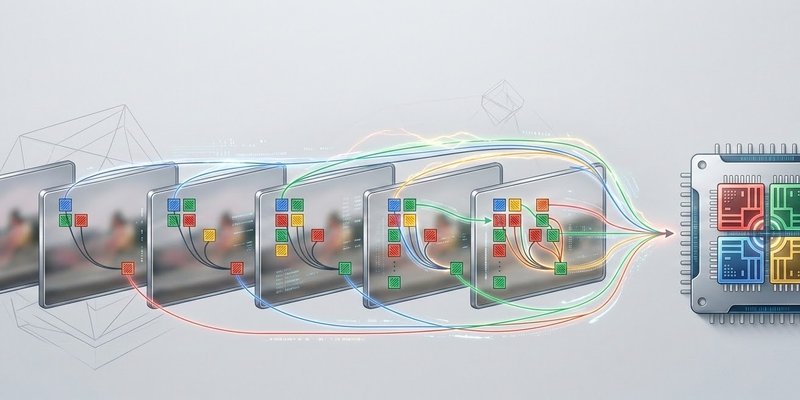
To address the quadratic latency bottleneck of self-attention in high-resolution video diffusion models, developers implemented Sparse VideoGen (SVG) to dynamically route attention heads to highly structured spatial or temporal sparse masks. Translating this algorithmic sparsity into physical hardware speedups on TPUs required optimizing the Splash Attention kernel by bypassing empty memory tiles, restricting exact coordinate masking strictly to boundary tiles, and permuting token memory layouts into temporal-major order for contiguous access. By aligning these sparse masks with actual hardware tile execution, the combined optimizations significantly reduced wasted matrix operations and achieved up to a 1.69x end-to-end inference speedup for 1440p video generation.
SEPT. 24, 2026 / AI
The MaxText team successfully reproduced Ai2’s Olmo 3 7B language model from scratch on Google Cloud TPUs using JAX/XLA, precisely matching the original PyTorch-on-GPU reference across pre-training and mid-training stages on all held-out evaluations. The implementation achieved up to 57.4% Model Flops Utilization (MFU) and demonstrated robust infrastructure portability by surviving mid-run cluster resizes and cross-generation TPU shifts without requiring recipe alterations. Crucially, the exercise proved the necessity of comprehensive held-out validation by catching a silent data-loader memorization bug that artificially depressed training loss and would have otherwise faked a performance win.