2862 results
NOV. 19, 2026 / AI
Streaming DiLoCo in MaxText enables developers to efficiently train large language models across geographically distributed TPU slices by streaming parameter fragments instead of synchronizing full models at every step. This approach slashes cross-slice communication volume by over 60× and eliminates network stalls, allowing seamless multi-datacenter scaling without degrading model convergence or quality.
NOV. 19, 2026 / AI
This post walks developers through training a multi-turn, tool-using LLM agent using Tunix and Gemma 4 on Cloud TPUs. By leveraging agentic Group Relative Policy Optimization (GRPO) and asynchronous vLLM rollouts, the approach significantly improves complex reasoning and tool compliance in interactive environments.

NOV. 17, 2026 / Web
Google AI Studio now lets developers build, test, and ship full-stack Kotlin Android apps from a single prompt—complete with Cloud Firestore, Firebase Authentication, Firebase AI Logic, a faster HD emulator with audio, visual screenshot debugging, and direct publishing to your personal Google Play library.

NOV. 17, 2026 / AI
Google's Gemini 4 Hydrogen brings strong spatial and embodied reasoning capabilities to a fast, efficient model built specifically for robotics. To help developers put these capabilities to work, the new Robotics plugin for Google Antigravity transforms the platform into a comprehensive workbench supporting rapid hardware bring-up, MuJoCo simulation, and closed-loop control. Developers can leverage these tools to transition from an unboxed robot arm to a fully functional real-to-sim-to-real application in an afternoon using natural language prompts and day-one support in the google-genai SDKs.
NOV. 17, 2026 / Mobile
Meet Another Build File Service (ABFS), Google's open-source content-addressable filesystem and build cache that cuts Android checkouts to <8s and builds to ~2m.
NOV. 16, 2026 / AI
The newly launched AI-Hypercomputer/tpu-codesign guide provides hardware-grounded design rules to help developers maximize performance on TPUs for LLMs and Mixture-of-Experts (MoE) workloads. Key principles include aligning reduction and output dimensions to 256 for systolic arrays, adopting LatentMoE to compress routed token traffic, and mapping parallel axes directly onto physical links.
NOV. 16, 2026 / AI
This guide walks developers through setting up Agent Anomaly Detection on the Gemini Enterprise Agent Platform to monitor AI agent telemetry and catch behavioral risks. It demonstrates how to deploy a sample customer support agent, trigger out-of-scope security findings, and configure proactive alerts using Cloud Monitoring and Security Command Center.

NOV. 16, 2026 / AI
AI agent sessions remain active and idle for most of the workday, making traditional one-Pod-per-session allocations inefficient for cluster resources. By using open-source tools like Agent Substrate and AX on GKE, developers can park idle sessions in object storage to release compute resources while maintaining session state. This approach optimizes resource utilization and reduces Kubernetes node costs by up to 40%.

NOV. 16, 2026 / AI
How we eliminated floating-point train–inference logprob drift for on-policy LLM reinforcement learning across 64 Cloud TPU v5p chips using a generalizable four-part JAX and Pallas recipe in Tunix.

NOV. 12, 2026 / AI
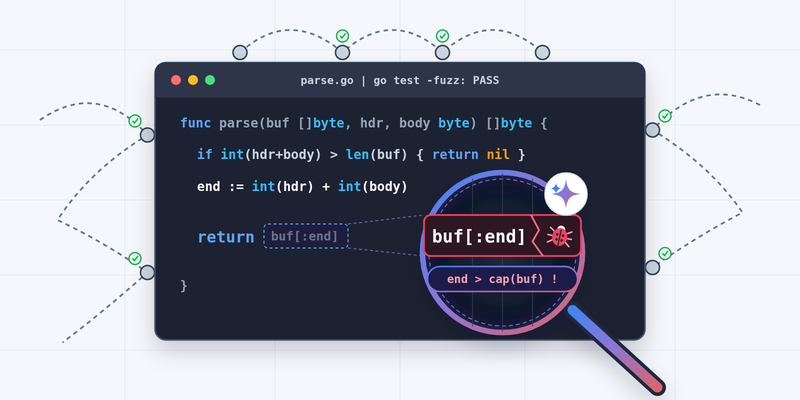
How pairing Go's surviving compiler bounds-check traps with Gemini 4 Argon and the Z3 constraint solver catches latent out-of-bounds panics in Go code and uncovers a slice-capacity blind spot in go test -fuzz.