522 results
NOV. 10, 2026 / Mobile
Google AI Edge Gallery now supports on-device, offline Automatic Speech Recognition (ASR) and Text-to-Speech (TTS) capabilities for building developer-friendly voice applications. Developers can leverage ML Kit for optimized Android performance, or use MediaPipe Tasks and LiteRT for cross-platform open-weight model integration. This local pipeline seamlessly pairs lightweight speech models with on-device small language models like Gemini Nano and Gemma 4 to enable real-time streaming transcription and low-latency synthesis.

NOV. 9, 2026 / Mobile
Developers can now build applications powered by Google Maps Platform directly within Google AI Studio by prompting Gemini with real-world geospatial concepts. The integration eliminates traditional configuration hurdles by providing one-click demo keys that generate instantly without requiring Cloud Console redirects or credit cards. This setup grants developers immediate access to core APIs—including Maps, Places, and Routes—supported by daily sandbox quotas for seamless prototyping.
NOV. 9, 2026 / AI
Google Cloud's MaxText framework now supports long-context training up to 14 million tokens on Cloud TPUs by implementing four context-parallel strategies: All-gather, A2A, P2P, and USP. Powered by the Tokamax Splash Attention kernel, these strategies effectively manage attention compute and memory bottlenecks without materializing full key-value sequences in high-bandwidth memory. Developers can adopt these capabilities in MaxText v0.2.4 to achieve high Model FLOPs Utilization (MFU) across large-scale model training workflows.

OCT. 28, 2026 / Mobile
LiteRT in Google Play services now offers GPU inference powered by ML Drift, delivering about 1.4x faster performance alongside the new CompiledModel API. Switching from bundled binaries reduces app size by approximately 8 MB while enabling seamless, automatic runtime updates across billions of devices. Developers can easily adopt these updates by updating their dependencies and utilizing the new Android Studio LiteRT skill for automated migration.
OCT. 27, 2026 / Mobile
A2UI now supports swappable inference formats, introducing A2UI Express which uses up to 3x fewer tokens and cuts latency by compiling compact Python-style syntax into standard A2UI JSON via Agent SDKs. Developers can also use controlled generation with TypeSafe's Jev system-decision models to render known-shape screens in under 300 ms while smaller models stream text. These updates require no changes to frontend renderers or component catalogs, offering flexible performance levers for generative UI development across Python, TypeScript, and Dart.

OCT. 26, 2026 / Web
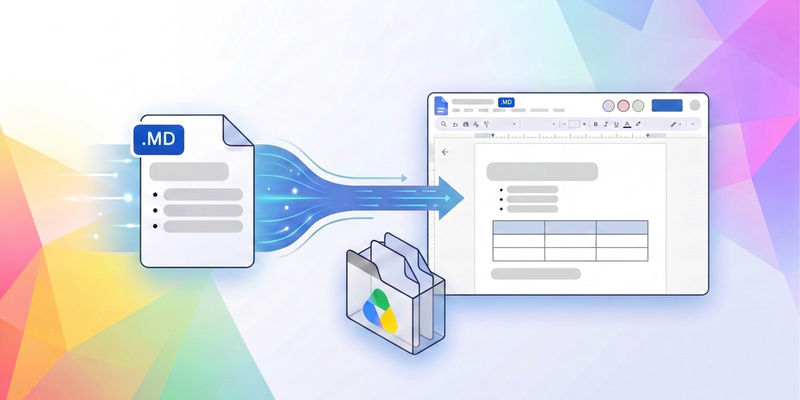
Google Workspace now offers native support for Markdown (.md) files, allowing developers and AI agents to seamlessly collaborate on documentation directly in Google Docs without manual file conversions. This integration preserves native file fidelity for use with Git repositories and developer tools while unlocking standard Docs features like line-level commenting, rendered Drive previews, and tracked version history.
OCT. 22, 2026 / Cloud
API Gateway now supports real-time streaming—including Server-Sent Events, WebSockets, gRPC, and chunked transfer encoding—in Public Preview without requiring changes to your existing API specifications. This update allows developers to route long-lived, bi-directional streams and AI workloads directly through the gateway while maintaining consistent authentication, rate limiting, and observability. Additionally, gateways now feature deterministic default hostnames, simplifying environment provisioning and infrastructure-as-code management.
OCT. 20, 2026 / AI
TorchTPU integrates a native torch.device("tpu") backend directly into PyTorch, allowing developers to train large-scale models on Google Cloud TPUs without rewriting code in JAX. The TorchTitan TPU fork enhances this with production-grade scaling primitives like SimpleFSDP, Graph Trainer, and custom Pallas kernels that achieve high Model Flops Utilization (MFU) across dense and MoE architectures. Developers can leverage these battle-tested optimization playbooks, recipes, and the Hugging Face modeling backend to efficiently scale their own workloads on TPU infrastructure.
OCT. 20, 2026 / AI
This post announces native PyTorch backends for vLLM and SGLang powered by TorchTPU, enabling developers to run and optimize serving workloads using familiar PyTorch tools. Built in collaboration with open-source project maintainers, these engines include optimized TPU kernel implementations, production-ready features like KV cache management with TPU Sync, and disaggregated serving. Public benchmarks demonstrate state-of-the-art performance and industry-leading cost efficiency on Ironwood TPU across long-context and agentic workloads.

OCT. 20, 2026 / Mobile
Google Research has completed the 32-bit open-source Coral NPU RISC-V architecture with the introduction of its Matrix Execution Unit, which delivers up to 1 TOPS while targeting 10 mW average power for edge inference. Alongside this architecture, the release of the v1.0 open-source IREE/MLIR compiler allows developers to take models from JAX, PyTorch, and TensorFlow straight to Coral NPU hardware without writing custom assembly. Developers can now prototype and deploy these multimodal edge applications using new hardware options like the Synaptics Astra SR200 MCU series and globally available Coralboard devkits.12
