89 results
OCT. 20, 2026 / AI
TorchTPU integrates a native torch.device("tpu") backend directly into PyTorch, allowing developers to train large-scale models on Google Cloud TPUs without rewriting code in JAX. The TorchTitan TPU fork enhances this with production-grade scaling primitives like SimpleFSDP, Graph Trainer, and custom Pallas kernels that achieve high Model Flops Utilization (MFU) across dense and MoE architectures. Developers can leverage these battle-tested optimization playbooks, recipes, and the Hugging Face modeling backend to efficiently scale their own workloads on TPU infrastructure.
OCT. 15, 2026 / Mobile
Google OAuth Platform now supports DPoP (Demonstrating Proof-of-Possession) to sender-constrain refresh tokens, neutralizing Infostealer malware and adversary-in-the-middle attacks. By cryptographically binding long-lived refresh tokens while maintaining short-lived access tokens as standard Bearer tokens, developers achieve robust credential security without incurring high-QPS API performance overhead. Additionally, developers integrating multi-agent or Model Context Protocol (MCP) workloads can use Google Cloud Secure Token Service (STS) to handle secure token delegation across agent chains.

OCT. 15, 2026 / AI
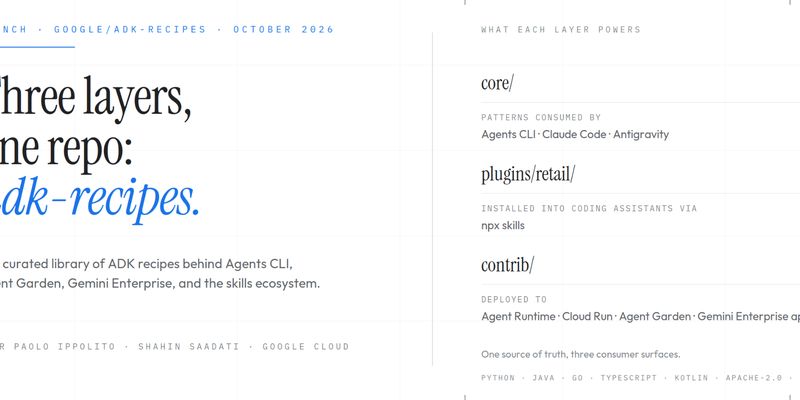
The google/adk-recipes repository unifies Agent Development Kit (ADK) resources into three structured layers—core/, plugins/, and contrib/—serving as a single source of truth for building AI agents. Developers can leverage reference patterns, install modular vertical skills (such as retail product search and virtual try-on) directly into their coding assistants, and deploy production-ready services across multiple languages. This cohesive structure streamlines the entire workflow from initial scaffolding to full deployment on Google Cloud infrastructure.
OCT. 8, 2026 / Mobile
Google AI Edge has introduced ML Drift, a high-performance, universal GPU compute framework designed to accelerate on-device AI and machine learning inference. By abstracting the complexities of hardware and low-level APIs—including OpenGL ES, OpenCL, Metal, and WebGPU—ML Drift enables developers to build real-time, interactive ML experiences, from sophisticated video effects to generative AI, across mobile and desktop platforms.

SEPT. 24, 2026 / AI
The MaxText team successfully reproduced Ai2’s Olmo 3 7B language model from scratch on Google Cloud TPUs using JAX/XLA, precisely matching the original PyTorch-on-GPU reference across pre-training and mid-training stages on all held-out evaluations. The implementation achieved up to 57.4% Model Flops Utilization (MFU) and demonstrated robust infrastructure portability by surviving mid-run cluster resizes and cross-generation TPU shifts without requiring recipe alterations. Crucially, the exercise proved the necessity of comprehensive held-out validation by catching a silent data-loader memorization bug that artificially depressed training loss and would have otherwise faked a performance win.
SEPT. 15, 2026 / AI
This blog post explores how to transition AI agents from static, build-time security controls to dynamic runtime governance using the Gemini Enterprise Agent Platform. It highlights three primary managed defenses: Model Armor for screening edge prompts, Semantic Governance Policies for evaluating tool intent against business rules, and Agent Anomaly Detection for catching multi-turn exploits. By shifting these capabilities to the platform level, security administrators can dynamically enforce policies and neutralize complex attacks without needing to modify or redeploy the agent's underlying code.

AUG. 26, 2026 / AI
Google Cloud has natively integrated TPU support into the vLLM serving engine, allowing developers to elastically scale high-demand embedding pipelines using Google Kubernetes Engine (GKE). To handle massive 15K+ token contexts for models like Qwen3-Embedding-8B, the engineering team implemented TPU-specific optimizations such as hardware-safe tensor alignment, JAX/XLA compilation pre-warming, and a hybrid StepPool architecture for chunked prefill management. These enhancements achieve near-perfect numerical parity with reference GPU baselines, and developers can immediately leverage the open-sourced setup recipes on the AI-Hypercomputer GitHub to build their own high-throughput semantic retrieval applications.

AUG. 17, 2026 / AI
Building autonomous AI agents that mutate production state requires moving beyond soft system prompts to a robust zero-trust architecture. To secure Google Agent Development Kit (ADK) workflows against prompt injections and malicious execution, developers must implement hardware-backed cryptographic signatures for database writes, kernel-level sandboxing with gVisor for dynamic code, and deterministic semantic gateways for I/O validation. By enforcing these hard security boundaries at the infrastructure level, you can safely deploy multi-tool AI agents without risking unauthorized data manipulation or server compromise.

AUG. 11, 2026 / AI
As AI coding assistants shift the developer's primary role from writing boilerplate to reviewing and maintaining systems, language choice becomes critical for long-term architectural integrity. Go directly addresses this new paradigm by utilizing its strict compiler, integrated toolchain, and uncompromising readability to provide deterministic guardrails that help AI models self-correct and generate highly standardized code. By enforcing ecosystem-wide consistency and strict backward compatibility, the Go platform empowers engineering teams to efficiently verify, optimize, and maintain high-velocity, AI-generated output in production environments.
JULY 21, 2026 / AI
Tunix is Google’s new JAX-native post-training library designed to eliminate TPU idling bottlenecks when training multi-turn, tool-using LLM reasoning agents. It maximizes hardware throughput by combining highly concurrent, asynchronous rollouts with a decoupled producer-consumer pipeline, ensuring the trainer is constantly fed even while agents wait on network I/O or environment steps. Additionally, Tunix provides plug-and-play abstractions and continuous macro-level profiling, allowing developers to easily integrate custom open-source environments and optimize complex distributed workflows without massive code rewrites.