79 results
NOV. 9, 2026 / AI
Google Cloud's MaxText framework now supports long-context training up to 14 million tokens on Cloud TPUs by implementing four context-parallel strategies: All-gather, A2A, P2P, and USP. Powered by the Tokamax Splash Attention kernel, these strategies effectively manage attention compute and memory bottlenecks without materializing full key-value sequences in high-bandwidth memory. Developers can adopt these capabilities in MaxText v0.2.4 to achieve high Model FLOPs Utilization (MFU) across large-scale model training workflows.

NOV. 3, 2026 / AI
Per-token API prices keep falling, yet engineering bills for autonomous coding agents keep climbing....

OCT. 29, 2026 / Mobile
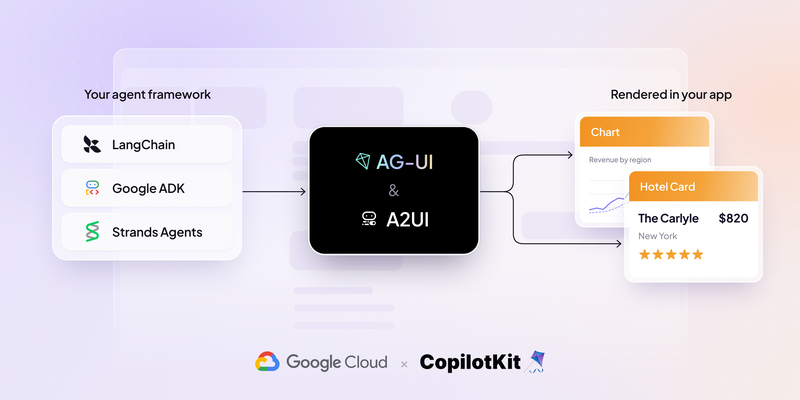
See Google A2Ui in action! Learn how to natively render agentic UIs across Langchain, AWS Strands, Microsoft agents, and Google ADK using CopilotKit SDKs for A2UI.
OCT. 20, 2026 / AI
TorchTPU integrates a native torch.device("tpu") backend directly into PyTorch, allowing developers to train large-scale models on Google Cloud TPUs without rewriting code in JAX. The TorchTitan TPU fork enhances this with production-grade scaling primitives like SimpleFSDP, Graph Trainer, and custom Pallas kernels that achieve high Model Flops Utilization (MFU) across dense and MoE architectures. Developers can leverage these battle-tested optimization playbooks, recipes, and the Hugging Face modeling backend to efficiently scale their own workloads on TPU infrastructure.
OCT. 14, 2026 / AI
Apigee hybrid 1.17.0 introduces native Model Context Protocol (MCP) support, enabling the MCP data plane to run directly within your own Kubernetes cluster. This architecture ensures that AI agent request traffic and tool execution remain entirely inside your infrastructure while pulling configuration updates from the control plane. Developers can expose OpenAPI 3.0.x specifications as discoverable MCP tools, leverage existing security policies and API products, and trace end-to-end requests using W3C trace context headers.

OCT. 13, 2026 / Gemini
How our engineering team ran Gemini 4 Argon unattended overnight with .agents/skills and /goal mode to cut in-memory session prep overhead by 40% in long sessions and speed up cold imports by 21% in Google's open-source Python Agent Development Kit (ADK).

OCT. 8, 2026 / Mobile
Google AI Edge has introduced ML Drift, a high-performance, universal GPU compute framework designed to accelerate on-device AI and machine learning inference. By abstracting the complexities of hardware and low-level APIs—including OpenGL ES, OpenCL, Metal, and WebGPU—ML Drift enables developers to build real-time, interactive ML experiences, from sophisticated video effects to generative AI, across mobile and desktop platforms.

OCT. 8, 2026 / AI
How do you keep improving an AI agent after the first 80%, once it serves real production traffic and silent quality regressions return HTTP 200 OK? We are open-sourcing AQuA (Ambient Quality Agent), a reference implementation that runs beside your production agent in Google Cloud, sweeps and verifies failure clusters against conversation transcripts, and diagnoses root causes anchored to the exact deployed source snapshot.

OCT. 7, 2026 / AI
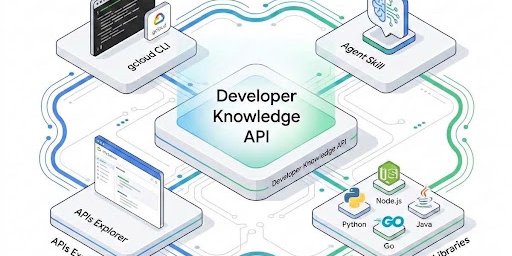
Google is launching the Developer Knowledge API and MCP Server in public preview. This new toolset provides a canonical, machine-readable way for AI assistants and agentic platforms to search and retrieve up-to-date documentation across Firebase, Google Cloud, Android, and more. By using the official MCP server, developers can connect tools directly to Google’s documentation corpus, ensuring that AI-generated code and guidance are based on authoritative, real-time context.
OCT. 6, 2026 / AI
EmbeddingGemma 2 is a compact, open-source multimodal embedding model that maps text, code, images, video, and audio into a unified 768-dimensional space. Developers can use the sentence-transformers library to selectively load modular modality encoders—ranging from 270M to 740M parameters—to optimize memory usage. Additionally, Matryoshka Representation Learning enables dynamic dimension truncation down to 128d, significantly reducing vector database storage requirements while maintaining high retrieval performance.